
At GTC 2020, NVIDIA announced updates to 80 SDKs, including tools to help you build AI-powered video streaming solutions, conversational AI, recommendation systems, and more.
Announcing NVIDIA Maxine
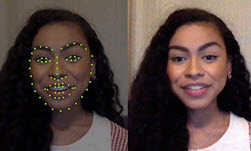
Today, we announced NVIDIA Maxine, a cloud-native video streaming AI platform for services such as video conferencing. It includes state-of-the-art AI models and optimized pipelines that can run several features in real time in the cloud.
Resources:
Sign up for early access to Maxine.
Announcing TensorRT 7.2
Today NVIDIA announced TensorRT 7.2, the latest version of its high-performance deep learning inference SDK.
Highlights include:
- 30x faster AI-effects compared to CPU for video-based workloads, enabling super-resolution, noise removal, and virtual backgrounds to run in real time.
- 2.5x faster recommenders with optimizations for fully connected layers used in MLPs
- 2x lower latency for RNNs compared to earlier, enables apps such as real-time fraud and anomaly detection
TensorRT 7.2 will be available in Q4, 2020 from the TensorRT page. The latest version of samples, parsers, and notebooks are always available in the TensorRT open source repo.
Add this GTC session to your calendar to learn more: Get the Highest Inference Performance using TensorRT
Announcing the NVIDIA Riva Open Beta
Today, NVIDIA announced Riva Open Beta, an accelerated SDK for enterprises to build multimodal conversational AI services that run in real-time on GPUs. It includes state-of-the-art DL models, tools for composing new models, transfer learning, and deployment, as well as optimized services that run under 300 ms latency. Riva cuts end-to-end conversational AI latency to half and offers 7x higher throughput compared to CPUs on the SpeechSquad benchmark.
As part of Riva, we also announced NeMo 1.0 Beta. NeMo is an open-source toolkit to develop state-of-the-art conversational AI models in three lines of code. In the latest version, you get:
- Simplified APIs based on PyTorch Lightning
- Built on PyTorch, interoperable with PyTorch modules
- Easy customization of models with popular Hydra framework integration.
This version of NeMo is optimized on A100 as well as earlier architectures with Tensor Cores. Get the new version of NeMo.
Resources:
- Introducing NVIDIA Riva: A GPU-Accelerated SDK for Developing Speech AI Applications
- NVIDIA NeMo: Fast development of speech and language models
- NVIDIA NeMo: Developing State-Of-The-Art Conversational AI Models in Three Lines Of Code (video)
Add these GTC sessions to your calendar to learn more:
Announcing NVIDIA Merlin Open Beta
Today NVIDIA announced the latest release of NVIDIA Merlin, an open beta application framework that enables the end-to-end development of deep learning recommender systems, from data preprocessing to model training and inference, all accelerated on NVIDIA GPUs. With this release, Merlin addresses common pain points around optimization and interoperability.
During preliminary testing, Merlin provides faster training on GPU in TensorFlow and PyTorch using our data loaders than default data loaders. This latest release reaffirms the NVIDIA commitment to accelerating the workflow of researchers, data scientists, and machine learning engineers and democratizing the development of large-scale, deep learning recommender systems.
Add this GTC session to your calendar to learn more:
- A Deep Dive into the Merlin Recommendation Framework
- Winning the 2020 RecSys Challenge with Kaggle Grandmasters
Resources:
- Accelerating Recommender Systems Training with NVIDIA Merlin Open Beta
- Announcing the NVIDIA NVTabular Open Beta with Multi-GPU Support and New Data Loaders
Register for GTC this week for more on the latest GPU-accelerated AI technologies.
