parallel programming
Aug 07, 2024
Profit and Loss Modeling on GPUs with ISO C++ Language Parallelism
The previous post How to Accelerate Quantitative Finance with ISO C++ Standard Parallelism demonstrated how to write a Black-Scholes simulation using ISO C++...
10 MIN READ
Mar 06, 2024
How to Accelerate Quantitative Finance with ISO C++ Standard Parallelism
Quantitative finance libraries are software packages that consist of mathematical, statistical, and, more recently, machine learning models designed for use in...
10 MIN READ
Nov 13, 2023
Simplifying GPU Programming for HPC with NVIDIA Grace Hopper Superchip
The new hardware developments in NVIDIA Grace Hopper Superchip systems enable some dramatic changes to the way developers approach GPU programming. Most...
17 MIN READ
Nov 13, 2023
Optimize Energy Efficiency of Multi-Node VASP Simulations with NVIDIA Magnum IO
Computational energy efficiency has become a primary decision criterion for most supercomputing centers. Data centers, once built, are capped in terms of the...
17 MIN READ
Nov 17, 2022
New Asynchronous Programming Model Library Now Available with NVIDIA HPC SDK v22.11
Celebrating the SuperComputing 2022 international conference, NVIDIA announces the release of HPC Software Development Kit (SDK) v22.11. Members of the NVIDIA...
4 MIN READ
Nov 15, 2022
Scaling VASP with NVIDIA Magnum IO
You could make an argument that the history of civilization and technological advancement is the history of the search and discovery of materials. Ages are...
22 MIN READ
Jul 14, 2022
Introducing NVIDIA CUDA-Q: The Platform for Hybrid Quantum-Classical Computing
The past decade has seen quantum computing leap out of academic labs into the mainstream. Efforts to build better quantum computers proliferate at both...
8 MIN READ
Apr 28, 2022
Boosting Inline Packet Processing Using DPDK and GPUdev with GPUs
The inline processing of network packets using GPUs is a packet-analysis technique useful to a number of different application domains: signal processing,...
14 MIN READ
Apr 18, 2022
Multi-GPU Programming with Standard Parallel C++, Part 2
It may seem natural to expect that the performance of your CPU-to-GPU port will range below that of a dedicated HPC code. After all, you are limited by the...
13 MIN READ
Apr 18, 2022
Multi-GPU Programming with Standard Parallel C++, Part 1
The difficulty of porting an application to GPUs varies from one case to another. In the best-case scenario, you can accelerate critical code sections by...
17 MIN READ
Jan 12, 2022
Developing Accelerated Code with Standard Language Parallelism
The NVIDIA platform is the most mature and complete platform for accelerated computing. In this post, I address the simplest, most productive, and most...
12 MIN READ
Apr 15, 2021
Exploring the New Features of CUDA 11.3
CUDA is the software development platform for building GPU-accelerated applications, providing all the components you need to develop applications that use...
10 MIN READ
Dec 16, 2020
Enhancing Memory Allocation with New NVIDIA CUDA 11.2 Features
CUDA is the software development platform for building GPU-accelerated applications, providing all the components needed to develop applications targeting...
9 MIN READ
Aug 07, 2020
Bringing Tensor Cores to Standard Fortran
Tuned math libraries are an easy and dependable way to extract the ultimate performance from your HPC system. However, for long-lived applications or those...
10 MIN READ
Jun 26, 2020
CUDA Refresher: The CUDA Programming Model
This is the fourth post in the CUDA Refresher series, which has the goal of refreshing key concepts in CUDA, tools, and optimization for beginning or...
7 MIN READ
May 21, 2020
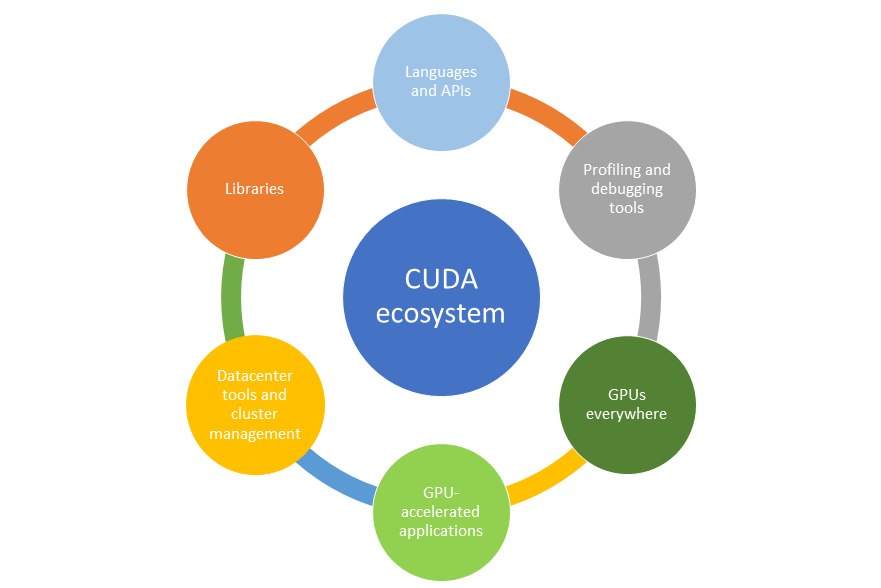
CUDA Refresher: The GPU Computing Ecosystem
This is the third post in the CUDA Refresher series, which has the goal of refreshing key concepts in CUDA, tools, and optimization for beginning or...
8 MIN READ