Transformers
Jun 16, 2026
How to Optimize Transformer-Based Models for Low-Precision Training
Transformer architectures are the backbone of many modern large language and generative AI models. As these models grow in size, training runs consume more GPU...
9 MIN READ
May 01, 2025
Boosting Matrix Multiplication Speed and Flexibility with NVIDIA cuBLAS 12.9
The NVIDIA CUDA-X math libraries empower developers to build accelerated applications for AI, scientific computing, data processing, and more. Two...
8 MIN READ
Jul 11, 2024
Next Generation of FlashAttention
NVIDIA is excited to collaborate with Colfax, Together.ai, Meta, and Princeton University on their recent achievement to exploit the Hopper GPU architecture...
1 MIN READ
Jun 12, 2024
Introducing Grouped GEMM APIs in cuBLAS and More Performance Updates
The latest release of NVIDIA cuBLAS library, version 12.5, continues to deliver functionality and performance to deep learning (DL) and high-performance...
7 MIN READ
Jan 29, 2024
Emulating the Attention Mechanism in Transformer Models with a Fully Convolutional Network
The past decade has seen a remarkable surge in the adoption of deep learning techniques for computer vision (CV) tasks. Convolutional neural networks (CNNs)...
13 MIN READ
Nov 17, 2023
Mastering LLM Techniques: Inference Optimization
Stacking transformer layers to create large models results in better accuracies, few-shot learning capabilities, and even near-human emergent abilities on a...
26 MIN READ
Jul 25, 2023
Improve Accuracy and Robustness of Vision AI Apps with Vision Transformers and NVIDIA TAO
Vision Transformers (ViTs) are taking computer vision by storm, offering incredible accuracy, robust solutions for challenging real-world scenarios, and...
5 MIN READ
May 15, 2023
Efficiently Scale LLM Training Across a Large GPU Cluster with Alpa and Ray
Recent years have seen a proliferation of large language models (LLMs) that extend beyond traditional language tasks to generative AI. This includes models...
16 MIN READ
Feb 01, 2023
New cuBLAS 12.0 Features and Matrix Multiplication Performance on NVIDIA Hopper GPUs
The NVIDIA H100 Tensor Core GPU, based on the NVIDIA Hopper architecture with the fourth generation of NVIDIA Tensor Cores, recently debuted delivering...
10 MIN READ
Sep 14, 2022
NVIDIA, Arm, and Intel Publish FP8 Specification for Standardization as an Interchange Format for AI
AI processing requires full-stack innovation across hardware and software platforms to address the growing computational demands of neural networks. A key area...
4 MIN READ
Sep 12, 2022
Improving Japanese Language ASR by Combining Convolutions with Attention Mechanisms
Automatic speech recognition (ASR) research generally focuses on high-resource languages such as English, which is supported by hundreds of thousands of hours...
5 MIN READ
Aug 03, 2022
Accelerated Inference for Large Transformer Models Using NVIDIA Triton Inference Server
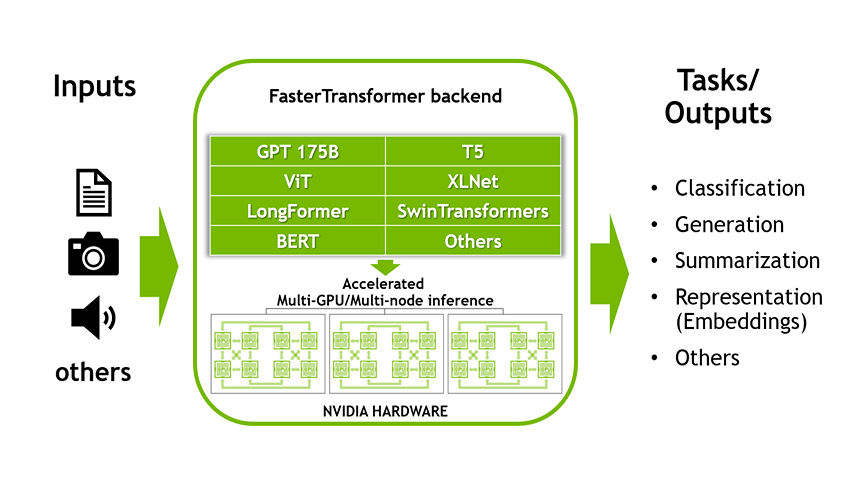
This is the first part of a two-part series discussing the NVIDIA Triton Inference Server’s FasterTransformer (FT) library, one of the fastest libraries for...
10 MIN READ
Aug 03, 2022
Deploying GPT-J and T5 with NVIDIA Triton Inference Server
This is the second part of a two-part series about NVIDIA tools that allow you to run large transformer models for accelerated inference. For an introduction...
16 MIN READ
Jul 28, 2022
NVIDIA AI Platform Delivers Big Gains for Large Language Models
As the size and complexity of large language models (LLMs) continue to grow, NVIDIA is today announcing updates to the NeMo framework that provide training...
7 MIN READ
Jul 27, 2022
Developing NLP Applications for Healthcare
Natural language processing (NLP) can be defined as the combination of artificial intelligence (AI), computer science, and computational linguistics to...
4 MIN READ
Jul 12, 2022
Adapting P-Tuning to Solve Non-English Downstream Tasks
With the increasing demand for access to pretrained large language model (LLM) weights, the climate around LLM sharing is changing. Recently, Meta released...
15 MIN READ