Researchers, developers, and engineers from all over the world are gathering virtually this year for the European Conference on Computer Vision (ECCV) 2020.
Among the papers being presented by NVIDIA researchers at ECCV this year, COCO-FUNIT: Few-Shot Unsupervised Image Translation with a Content Conditioned Style Encoder offers significant visual improvements to the popular GANimal demo featured on the AI Playground.
The researchers Kuniaki Saito, Kate Saenko, and Ming-Yu Liu present a model that effectively addressees previous content loss problems. The Image-to-Image translation successfully preserves the structure of the input content image, like a fluffy white puppy, while emulating the appearance of the unseen domain, a snow leopard. This generates a photorealistic translation of a puppy with a coat in the style of the snow leopard.
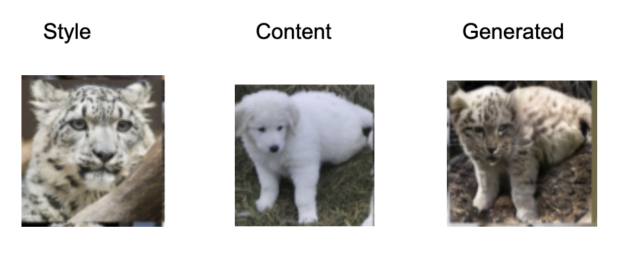
The researchers benchmarked their method using four datasets representing Carnivores, Mammals, Birds, and Motorbikes. This produced visually compelling images across a variety of subjects and poses.
For code and pretrained models, please check out https://nvlabs.github.io/COCO-FUNIT/
Additional papers being presented at ECCV by NVIDIA researchers and collaborators include:
- Learning Object Permanence from Video
- Learning Canonical Representations for Scene Graph to Image Generation
- Contrastive Learning for Weakly Supervised Phrase Grounding
- Joint Disentangling and Adaptation for Cross-Domain Person Re-Identification
- Self-supervised Single-view 3D Reconstruction via Semantic Consistency
- Lift, Splat, Shoot: Encoding Images From Arbitrary Camera Rigs by Implicitly Unprojecting to 3D
Github
- Weakly Supervised 3D Hand Pose Estimation via Biomechanical Constraints
- UFO2: A Unified Framework towards Omni-supervised Object Detection
Github - DeepGMR: Learning Latent Gaussian Mixture Models for Registration
- Measuring Generalisation to Unseen Viewpoints, Articulations, Shapes and Objects for 3D Hand Pose Estimation under Hand-Object Interaction
- Simulating content consistent vehicle datasets with attribute descent
Github - COCO-FUNIT: Few-Shot Unsupervised Image Translation with a Content Conditioned Style Encoder
Github - World-Consistent Video-to-Video Synthesis
Github
- Learning Object Permanence from Video
Github - Learning Canonical Representations for Scene Graph to Image Generation
Github - Generative Sparse Detection Networks for 3D Single-shot Object Detection
- SceneCAD: Predicting Object Alignments and Layouts in RGB-D Scans
- RubiksNet: Learnable 3D-Shift for Efficient Video Action Recognition
- Meta-Sim2: Unsupervised Learning of Scene Structure for Synthetic Data Generation
- ScribbleBox: Interactive Annotation Framework for Video Object Segmentation
- Interactive Annotation of 3D Object Geometry
- Beyond Fixed Grid: Learning Geometric Image Representation with a Deformable Grid
- Expressive Telepresence via Modular Codec Avatar, European Conference on Computer Vision