Data Science

NVIDIA Deep Learning SDK Update for Volta Now Available

AI-Generated Summary

  • cuDNN 7 accelerates deep learning training with up to 2.5x faster ResNet50 and 3x faster NMT LSTM RNN performance on Tesla V100 versus Tesla P100.
  • The library leverages mixed-precision Tensor Core operations on Volta GPUs for accelerated convolutions.
  • New grouped convolutions support models such as ResNeXt and Xception, and a CTC loss layer enables temporal classification tasks.
  • NCCL 2 delivers over 90% multi-node scaling efficiency across up to 8 GPU-accelerated servers.
  • The communication library performs automatic topology detection to determine optimal communication paths and is optimized for high bandwidth over PCIe and NVLink interconnects.

Next Steps

  • Visit the cuDNN 7 product page to learn more and download.
  • Visit the NCCL 2 product page to learn more and download.
Powered by NVIDIA Nemotron. AI-generated content may summarize information incompletely. Verify important information. Learn more

At GTC 2017, NVIDIA announced Volta optimized updates to the NVIDIA Deep Learning SDK. Today, we’re making these updates available as free downloads to members of the NVIDIA Developer Program.
Deep learning frameworks using NVIDIA cuDNN 7 and NCCL 2 can take advantage of new features and performance benefits of the Volta architecture.
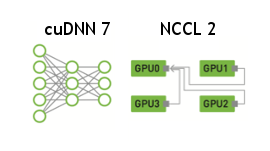
cuDNN 7

  • Up to 2.5x faster training of ResNet50 and 3x faster training of NMT language translation LSTM RNNs on Tesla V100 vs. Tesla P100
  • Accelerated convolutions using mixed-precision Tensor Cores operations on Volta GPUs
  • Grouped Convolutions for models such as ResNeXt and Xception and CTC (Connectionist Temporal Classification) loss layer for temporal classification tasks

NCCL 2

  • Delivers over 90% multi-node scaling efficiency using up to 8 GPU-accelerated servers
  • Performs automatic topology detection to determine optimal communication path
  • Optimized to achieve high bandwidth over PCIe and NVLink high-speed interconnect

Left: Caffe2 performance (images/sec), Tesla K80 + cuDNN 6 (FP32), Tesla P100 + cuDNN 6 (FP32), Tesla V100 + cuDNN 7 (FP16). ResNet50, Batch size: 64. Right: Microsoft Cognitive Toolkit multi-node scaling performance (images/sec), NVIDIA DGX-1 + cuDNN 6 (FP32), ResNet50, Batch size: 64

Learn more about Volta’s Tensor Cores and multi-node scaling of deep learning training

Visit the cuDNN 7 and NCCL 2 product pages to learn more and download >
Discuss (0)

Tags