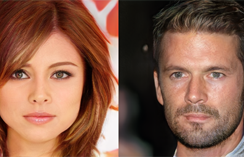
Researchers from NVIDIA recently published a paper detailing their new methodology for generative adversarial networks (GANs) that generated photorealistic pictures of fake celebrities.
One of the hottest topics in deep learning is GANs, which have the potential to create systems that learn more with less help from humans. Rather than train a single neural network to recognize pictures, researchers train two competing networks. The sparring networks learn from each other. As one works hard to find fake images, for example, the other gets better at creating fakes that are indistinguishable from the originals.
“The key idea is to grow both the generator and discriminator progressively: starting from a low resolution, we add new layers that model increasingly fine details as training progresses,” explained the researchers in their paper Progressive Growing of GANs for Improved Quality, Stability and Variation. “This both speeds the training up and greatly stabilizes it, allowing us to produce images of unprecedented quality.”
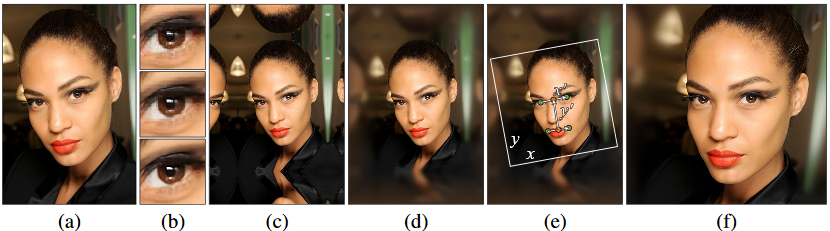
Since the publicly available CelebFaces Attributes (CelebA) training dataset varied in resolution and visual quality — and not sufficient enough for high output resolution — the researchers generated a higher-quality version of the dataset consisting of 30,000 images at 1024 x 1024 resolution.
Using a single Tesla P100 GPU, CUDA and cuDNN with Theano and Lasagne, the team trained their network for 20 days after which there were no longer observed qualitative differences between the results of consecutive training iterations.
Generating convincing realistic images with GANs are within reach and the researchers plan to use TensorFlow and multi-GPUs for the next part of the work.
Read more >
Generating Photorealistic Images of Fake Celebrities with Artificial Intelligence
Oct 30, 2017
Discuss (0)
AI-Generated Summary
- NVIDIA researchers developed a progressive growing methodology for generative adversarial networks that starts training at low resolution and adds layers to model finer details, improving quality, stability, and training speed.
- The team created the CelebA-HQ dataset of 30,000 images at 1024 x 1024 resolution by enhancing the original CelebA dataset through JPEG artifact removal, 4x super-resolution, mirror padding, Gaussian filtering, and high-quality resampling.
- Training on a single Tesla P100 GPU with CUDA and cuDNN using Theano and Lasagne for 20 days produced results with no qualitative differences between consecutive iterations.
Next Steps
- Read the Progressive Growing of GANs for Improved Quality, Stability and Variation paper for the full methodology and results.
Powered by NVIDIA Nemotron. AI-generated content may summarize information incompletely. Verify important information. Learn more
About the Authors