
Today, NVIDIA is announcing the availability of cuSPARSELt version 0.1.0. This software can be downloaded now free for members of the NVIDIA Developer Program.
What’s New
- Support for Window 10 (x86_64)
- Support for Linux ARM
- Introduced SM 8.6 Compatibility
- Support for TF32 compute type
- Better performance for SM 8.0 kernels (up to 90% SOL)
- Position independent sparseA / sparseB
- New APIs for compression and pruning
- Decoupled from cusparseLtMatmulPlan_t
See the cuSPARSELt Release Notes for more information
About cuSPARSELt
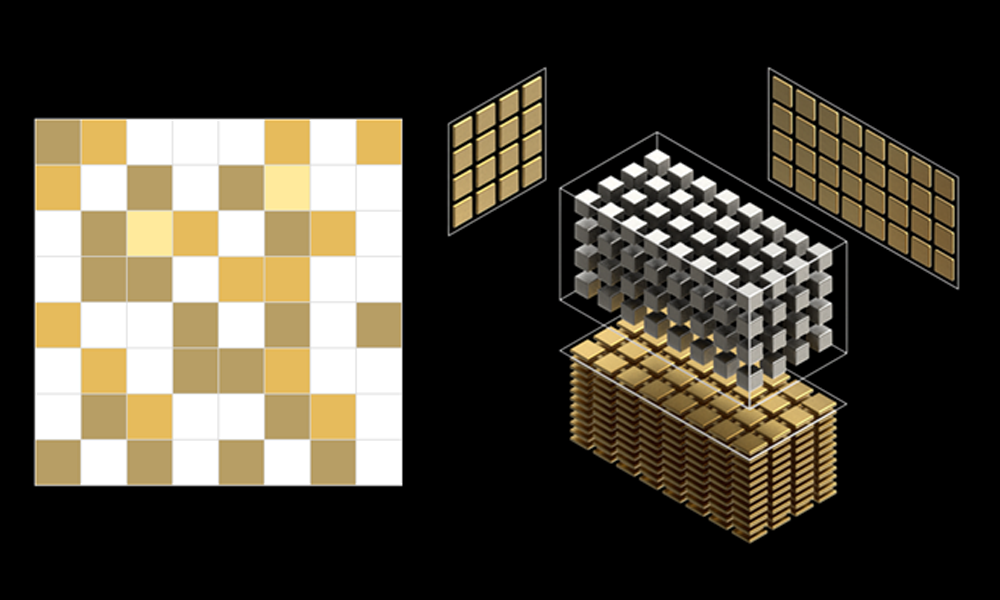
NVIDIA cuSPARSELt is a high-performance CUDA library dedicated to general matrix-matrix operations in which at least one operand is a sparse matrix:
\(D=\alpha op(A) \cdot op(B) + \beta op(C)\)
In this formula, \(op(A)\) and \(op(B)\) refer to in-place operations such as transpose/non-transpose.
The cuSPARSELt APIs allow flexibility in the algorithm/operation selection, epilogue, and matrix characteristics, including memory layout, alignment, and data types.
Key features:
- NVIDIA Sparse MMA tensor core support
- Mixed-precision computation support:
- FP16 input/output, FP32 Tensor Core accumulate
- BFLOAT16 input/output, FP32 Tensor Core accumulate
- INT8 input/output, INT32 Tensor Core compute
- FP32 input/output, TF32 Tensor Core compute
- TF32 input/output, TF32 Tensor Core compute
- Matrix pruning and compression functionalities
- Auto-tuning functionality (see cusparseLtMatmulSearch())
Learn more:
- GTC 2021: S31754 Recent Developments in NVIDIA Math Libraries
- GTC 2021: S31286 A Deep Dive into the Latest HPC Software
- GTC 2021: CWES1098 Tensor Core-Accelerated Math Libraries for Dense and Sparse Linear Algebra in AI and HPC
- cuSPARSELt Product Documentation
Recent Developer Blog posts:
